Jev 1.14 Update: Images, Box Localization, and 262k Context
Jev 1.14.0 arrived on October 14, 2026. Alongside the model update, TypeSafe AI opened experimental image input, Box localization, and longer context. The decision interface can now take part in visual workflows.
New to Jev? Start with our earlier introduction to Jev, System One models, and probabilistic decisions for Choice, Score, and Noul. This follow-up covers the changes documented as of October 17, 2026. It draws on official announcements and documentation; we have not run paid API benchmarks for this article.
Check the model name: jev-latest still points to 1.13
The official model reference lists these mappings at the time of writing:
| Name in your request | Current target |
|---|---|
| jev-latest | jev-1.13.0 |
| jev-preview | jev-1.14.0 |
| jev-1.14.0 | Pins version 1.14.0 |
I would use the explicit version to reproduce results. An alias can move even when your application code stays the same. Both versions currently cost $0.042 per million input tokens, with free output.
The release announcement identifies multilingual support as the largest expected improvement and schedules the jev-latest update for a week later. That is a plan, not evidence the switch has already happened. Gains on your own non-English workload still need evaluation.
Images can supply both the input and the criteria
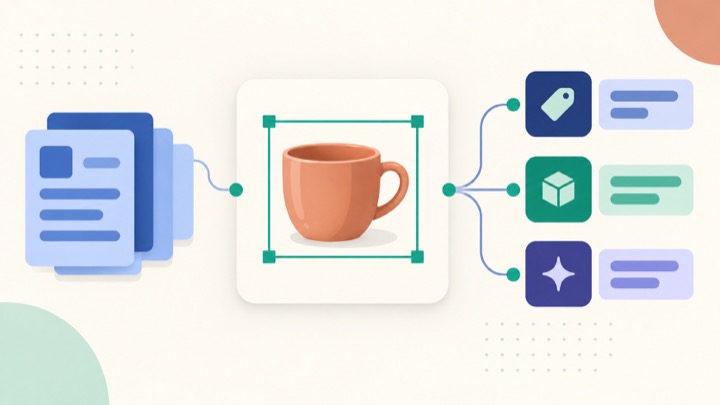
The image documentation allows pictures in state, instructions, and criteria. A product classifier, for example, could receive a product photo and reference pictures defining its categories.
Image support is also enabled for 1.13. It remains an experimental Danger Zone feature: include TypeSafe-Danger-Zone-Images: true in each relevant request. TypeSafe does not yet consider its reliability ready for production.
I would start with one narrow visual decision. Testing whether a photo matches a clearly defined category gives you a more useful starting point than asking the model to interpret an entire scene and handle every possible action.
Box returns a location, including when the target is absent
The new Box question requires 1.14 and returns one bounding box. Its top, bottom, left, and right edges are fractions from 0 to 1, relative to the image’s height or width. See the Box reference.
The catch is that Box has no “not found” result. An absent target still produces coordinates. Add a Noul question asking whether the object exists, then decide in code whether to use the box.
The following unexecuted example follows the documented HTTP image upload format. Supply your own product.jpg and set TYPESAFE_API_KEY in your environment. Running it uses your account’s API allowance.
1 | curl https://api.typesafe.ai/v1/systemone \ |
Valid coordinates are only the starting point. I would include absent objects, blurred images, and multiple similar objects in the test set before using the result downstream.
Context can reach 262k, but keep the input focused
The context reference gives defaults of 64k per request and 32k per question. Adding TypeSafe-Danger-Zone-Long-Context: true raises both limits to 262k tokens, on either 1.13 or 1.14.
Long context requires opting in. TypeSafe warns that it is slower and less accurate. For a support classifier, I would retrieve the relevant records first and expand the context only when the task needs it.
The SDK updates include a new Node.js requirement
Check the client environment as well as the model ID:
- Python SDK 0.7.5 adds image assets and Box support, with zstd request compression enabled by default.
- JavaScript SDK 0.7.0 adds images and Box, requires Node.js 22 or newer, and stops exporting request payload types.
If a service still runs on Node.js 18 or 20, I would validate the runtime upgrade separately from the model comparison. That makes compatibility failures easier to trace.
A customer case offers a useful starting point
TypeSafe’s October 7 Jack & Jill case study reports candidate prescreening costs falling from $0.755 to $0.092 per thousand candidates. These are vendor-published results for a particular customer workflow, not a universal savings forecast.
The useful lesson for me is to start with one high-volume step whose outputs are clearly bounded. Measure both cost and task quality before expanding its role.
Separate a valid response from a correct decision
A response can satisfy its type constraints and still be wrong. The System One documentation explicitly distinguishes calibration from a guarantee that any individual answer is correct. Read the earlier article’s “zero hallucinations” wording in the context of constrained output types and options, rather than guaranteed business accuracy.
The current confidence reference also clarifies that Choice and Score return confidence, while Noul returns a yes/no probability without a separate confidence field. When implementing the earlier examples, follow the current official response schema.
My upgrade approach would be to retain the old version as a baseline, compare mistakes, missed cases, latency, and cost on the same dataset, then adjust automation thresholds. Evaluate images, Box, and long context separately before adding them to an existing workflow.
For help choosing that first task, continue with our original Jev guide: three decision primitives, five use cases, and open-source tools. A clearly defined decision gives you a concrete way to judge whether these new capabilities help.


